Seen on X

What people are building with Laya.

Demos, games, ports and benchmarks posted on X, picked by hand. Each one links back to the original post and, where there is one, to the project in the directory.

Raya routes models with a Laya fine-tune, scoring 80.3% on 563 prompts

Yesterday I tested open-source routers against Jev, they sucked. Instead of waiting for @typesafeai to deploy in EU, I fine tuned Laya on routing tasks. Meet Raya: Fine-tuned for model routing based on Laya. Open weights, runs in the EU. 🇪🇺 Same 563 prompts, 14 languages: Jev: 70.5% Raya: 80.3% Within 4 points of Jev. 20× faster. $0 per call. @huggingface link in the reply ⬇️

♥ 10↻ 12.3k viewsView on X

Jav routes iPhone assistant intents with a fine-tuned Laya model on-device

Apple pays Google $1 billion a year for Siri. I rebuilt it over the weekend with Jev. Meet Jav, an assistant that makes decisions faster thanks to Laya, the open-weight alternative to Jev, running entirely on-device with CoreAI. I fine-tuned it on 10,000 intent samples covering around 100 different actions an iPhone assistant might need to take. It takes a request and decides what should happen: timer, reminder, calendar event, music, weather... Laya makes the routing decision in around 100 ms. Surprisingly, the bottleneck comes from Apple's own Foundation Model and App Intents APIs. Decisions are solved, now let's make actions smarter and faster with another on device model.

♥ 10↻ 21.5k viewsView on X

An arbiter uses Laya to drive six games at real-time speed

Arbiter using Laya drives six games, one decision per move. Paddle gets 32 moves a second. The Flappy clone asks one yes or no per frame and flies at 0.975 AUROC, minesweeper judges twelve cells in one call, 137 ms, and crossing gets a move and a hit-risk score from one call. It sits next to the LLM in about 5 GB. The video isn't sped up. That's the original speed.

♥ 10↻ 2870 viewsView on X

Laya beats Jev in a local Tetris speed test on a MacBook Air

WOW 😳 Laya took down Jev in a head-to-head Tetris match built with @grok 4.7. Jev ran in the cloud and needed 316 milliseconds to make a decision. Laya, an open weights System One model, ran locally on a 16GB MacBook Air and needed 44 milliseconds. That is 11 times faster, on a laptop, against a cloud model with presumably more compute behind it. Jev stacked up, ran out of room, and hit game over. Laya just kept clearing lines. Local inference beat cloud inference at its own speed game, no data center required.

♥ 10↻ 1971 viewsView on X

How Laya handles fast, local typed decisions

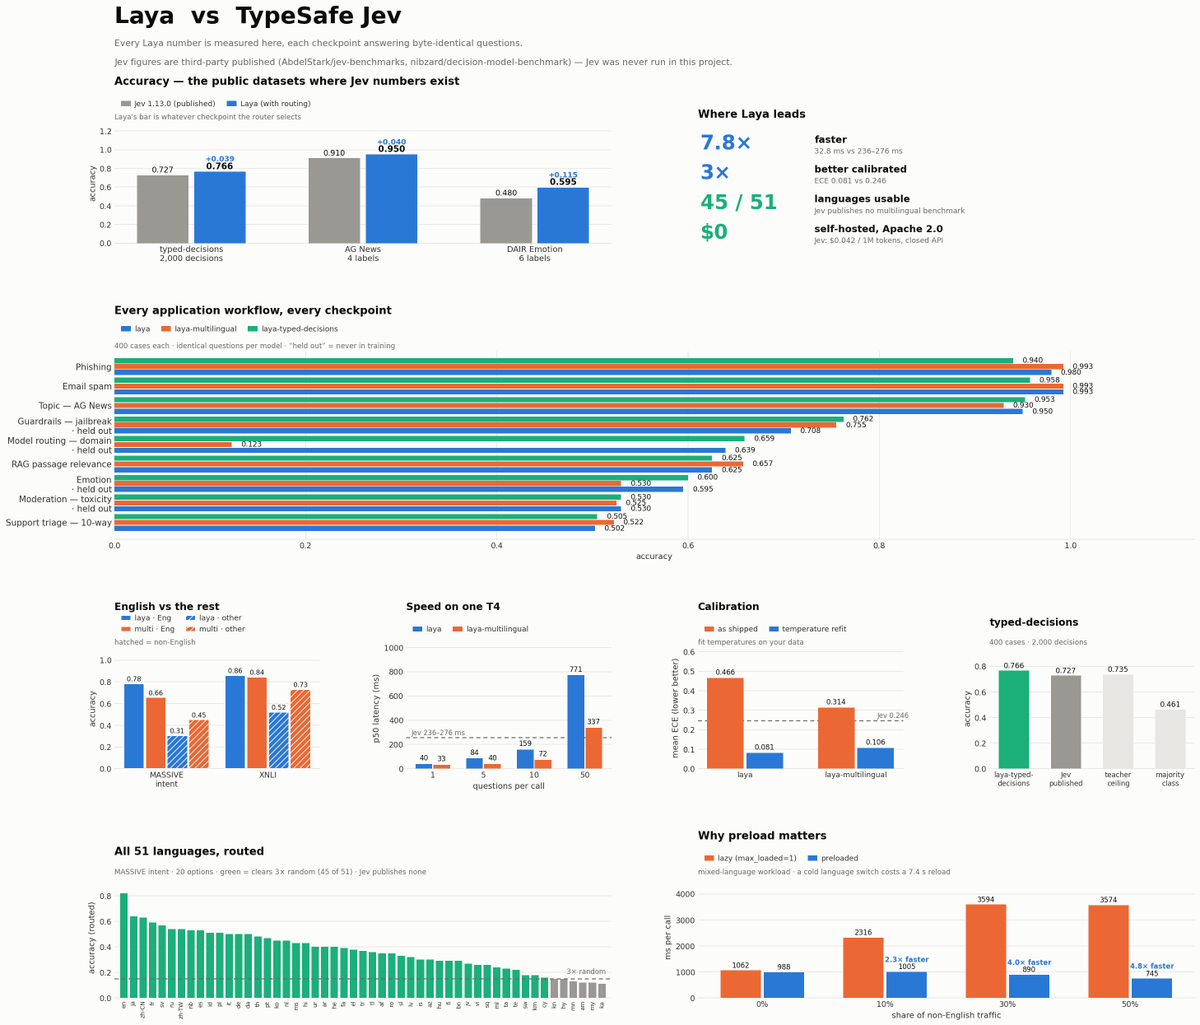
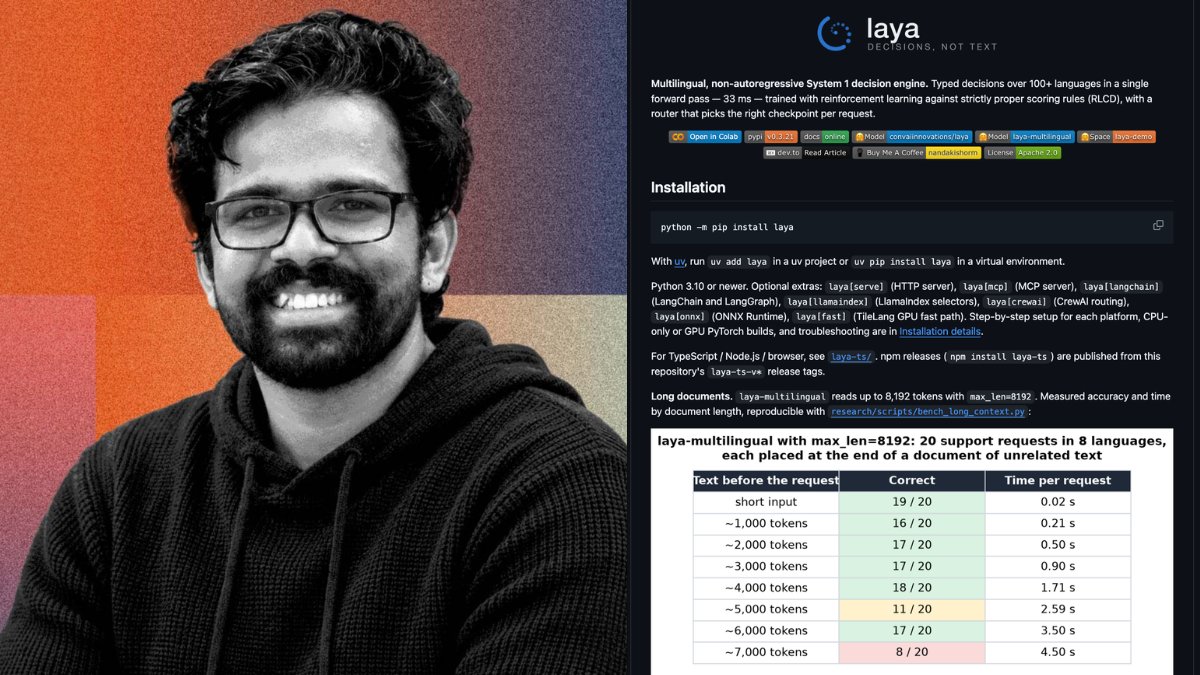
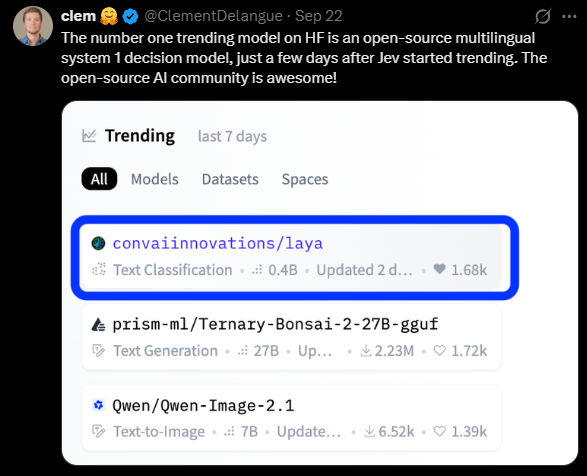
A solo engineer in Kerala, India built this over a year before Silicon Valley made it cool TypeSafe AI launched Jev on September 15th. A "System One" model. Instead of generating text, it makes fast decisions. Choice, score, yes or no Here's the thing nobody knew: Nandakishor M, founder of ConvAI Innovations in Kasaragod, Kerala, had been building the same idea since April 2025 It's called Laya. And it's open source - Single forward pass in ~33ms - Runs on less than 1GB of RAM - 100+ languages - Runs on your laptop. Even your phone - Apache 2.0. Free forever Jev charges $0.042 per million input tokens. Laya costs you your electricity bill Third party benchmarks put Jev at 236-276ms per decision. Laya is roughly 7x faster It hit #1 trending on Hugging Face. 3,500+ likes. The Hugging Face CEO himself praised it Is it perfect? No. You need to fine-tune it for your use case. Out of the box it's close to random. Short context window too But that's not the point The point is you do NOT need a massive LLM for every AI task. Routing a support ticket. Deciding which tool to call. Checking if a retrieved doc answers the question. A 1GB model handles that faster and for free Here's what I'd do: 1. Look at every LLM call in your app 2. Find the ones that just make a decision (yes/no, pick one, score this) 3. Swap them for a tiny local model like Laya 4. Watch your bill and latency drop You don't need Silicon Valley to build the future. You need an idea and a laptop

♥ 10↻ 41.1k viewsView on X
Project: laya→

Runware adds Laya to its System One API

Jev and Laya are now live on Runware 🎯 Two “System One” decision-making models: instead of generating text, they return a choice, a score, or a yes/no probability which your app can act on directly. - Jev, $0.042 / 1M input tokens - Laya, FREE for the first two weeks, until October 12, then $0.02 / 1M input tokens Available on Runware’s /v1/systemone API endpoint now.

♥ 10↻ 2450 viewsView on X

Laya’s reported single-GPU latency: 32.8 ms

He ran the model overnight on a train, and 12–15 hours later the first version of Laya was ready built on years of earlier research and experimentation. Four days after Jev launched, Nandakishor released Laya as open source, with a license that allowed commercial use. Laya is a 421-million-parameter model. On a single GPU, his published number is 32.8 milliseconds against 236–276 milliseconds cited for Jev. It briefly reached #1 on Hugging Face’s trending list. Then the internet noticed.

♥ 9↻ 11.3k viewsView on X

A visual guide compares generative LLMs with JEV and Laya decision models

Here is an architectural comparison between Normal LLMs vs Classification / Decision Models (like JEV and LAYA), since a lot of people treat every transformer as an autoregressive text generator. Normal LLM (Decoder-only) -> Predict what token comes next (causal masked attention) Classification Model (JEV / LAYA) -> Filter, score, and route in a single pass (bidirectional attention) The workflow pattern: Raw input/chunks -> Classification model (JEV / LAYA) -> triage & route -> pass only relevant context -> Normal LLM -> synthesize final response Why this matters: Instead of paying quadratic prefill and autoregressive token generation latency just to extract a JSON label or choose a tool, you use a fast single-pass encoder upstream to keep the generative context window lean. Sharing this as a visual reference for mental map.

♥ 9↻ 0351 viewsView on X

iii wraps Laya in a unified interface for agent tools

CLIs are a stop gap for agents. How many times have you watched your agent grep `gh --help` or re-read a file it just wrote? The problem is that CLIs seem like a great idea but every new session needs to rediscover how to use a given CLI, and then how to observe what the command did. It's this constant loop of discover functionality, execute, and discover how to observe that execution. Worse yet each and every tool varies in its discovery and execution steps. This is one of many reasons that I think iii makes a better system for agents: it is a system. All discovery, all execution has the same interface. Lately we've been enhancing existing tools for iii by wrapping them in our interface, we've done this with github, browser control, worktree, jev, laya, semif, email, claude-code, pi, codex, opencode, telegram, mcp, pdf reading, slack, computer use, document conversion, and so much more. Every single tool looks and behaves the exact same way, rather than the alternative of disjointed CLIs.

♥ 9↻ 1496 viewsView on X

Hermes nerve plugin offers Laya-powered agent supervision

今日爆款 Hermes 插件🔥 Hermes 会话体检台 + 监督神经 + 技能先过闸 + 出处托盘 + 云沙盒五连杀! 全网玩家把 Hermes 玩成了下一代「回合能复盘 + 每步有监工 + 技能不乱喷 + 打开过的源码能翻 + 命令跑进隔离舱」: 1️⃣ tommulkins/hermes-plugin-session-analyzer( Desktop 全页会话体检:token / cache / 成本、工具调用拆解、改文件账、失败分组,还能一键把分析提示丢进新草稿。 hermes plugins install session-dashboard “翻车第一次有体检报告,而不是翻二十屏 log 找那一行红字”! 2️⃣ keeltrace/hermes-nerve( 监督神经系统:Jev / Laya / OpenJev Reflex 可选,看板监工 + 上下文治理 + token 轨迹 + 持久 SSH worker。 hermes plugins install nerve “每一回合第一次有神经反射,而不是同一把锤子砸所有钉子”! 3️⃣ DECRUX9812/typesafe-skill-router( TypeSafe(Jev)技能路由:模型开口前先判该上哪一条技能,对不上就一行都不注入。 hermes plugins install typesafe-skill-router “技能第一次是点名上岗,而不是一千条 SKILL.md 全灌进上下文碰运气”! 4️⃣ aydnOktay/hermes-source-tray( 本回合 web_search / web_extract / browser_navigate 打开过的 URL,收成 Desktop 托盘 + /sources。 hermes plugins install source-tray “出处第一次有托盘,而不是链接散落在二十轮工具回包里”! 5️⃣ deepinfra/deepinfra-hermes-sandbox( 命令进 DeepInfra 云端微虚机:技能、缓存、凭据文件按工作区上舱,本机不再被 shell 直接掀桌。 hermes plugins install deepinfra-sandbox “施工第一次进隔离舱,而不是 Agent 在你笔记本根目录自由搏击”! // 这波直接把 Hermes 从「会自我进化的单兵」推到「回合可体检、决策有神经、技能先过闸、出处可翻、命令进沙盒」的完整操作系统。今晚装,明天值班台和隔离舱一起起飞。

♥ 9↻ 12.4k viewsView on X

quackd connects Laya decision models to robot adapters

Just a heads-up... I started building an open-source version of this AI <> Microduck use case that @romainhuet presented on the Dev Day stage already on August 28, before GPT-6 Astra even came out! Repeating, before GPT-6 Astra even came out! Anyway, the best thing about quackd is that it's an open-source CLI, which means no LLM vendor lock-in. Use @OpenAI, @AnthropicAI, @GeminiApp, @grok, or even local LLMs via @ollama or @vllm_project! Not only that, but quackd also supports VLAs and multiple decision LLMs (Jev by @typesafeai, Laya by @Nandakishorm1, Kev by @jaredpalmer). Plus, quackd has multiple robot adapters, which means robots can engage with each other as well to achieve a given goal. Can you imagine a @MicroDuckNVDA asking a @LeRobotHF SO-101 to hand it something from the table, drop it on the floor (not a glass, though), then Microduck picks it up with the beak and brings it to you? quackd is on a mission that PERFECTLY aligns with what Hugging Face is all about. I just need a real Microduck now that they have a few more in the France office to test quackd IRL. I'm even willing to fly from Slovenia to France to test it in their office under their terms! PS: I tried to contact @huggingface and @pollenrobotics multiple times over the past month to give me a chance, but no success so far. :( @Thom_Wolf @ClementDelangue @julien_c @jeffboudier @RemiFabreRobot @antoinepirrone @matth_lapeyre @RouanetPierre @darkseed

♥ 9↻ 5761 viewsView on X
Project: quackd→

Semantic Firewall combines Qdrant retrieval with Laya tool-call decisions

I built a Semantic Firewall using @qdrant_engine + Laya. Qdrant stores security policies + past decisions and retrieves the right context for each tool call using hybrid search. Allow → Ask → Block delete /build → Allow delete /production/customer_data.csv → Block Same action. Different context. 27/30 correct, with zero dangerous actions automatically allowed. Qdrant retrieves. Laya decides. The firewall enforces.

♥ 8↻ 0185 viewsView on X
Project: -Semantic-Firewall-laya→

Japanese Laya decision model reaches 85.75% accuracy on MLX

週末の成果。M5 Maxで動く日本語の判断器作った。完全一致のキャッシュ層、LayaのendoderをModernBERT-ja-310Mに差し替えてMLXで追加学習。日本語の公開データ35ソース13.6万件+合成データ。4BQwen3.5-4B派生、Qwen3.5-35B-A3B派生の4段階構成。未使用400問で正答率85.75%、平均約98ms、確率つき。同じ問いは0.3ms未満。実際にやってみると学びがあるね。1つのモデルで品質と速度の両立はムズかった。

♥ 8↻ 11.9k viewsView on X

Posted a Laya demo on X? Mention “Laya” and it gets picked up automatically, or submit the project.