
Runware explains Laya, Jev, and how to use decision models
Following the @typesafeai Jev, Laya, and System One model news? Our write-up covers what this new class of models do, how the two compare, and how to use them on Runware.
Seen on X
Demos, games, ports and benchmarks posted on X, picked by hand. Each one links back to the original post and, where there is one, to the project in the directory.
Following the @typesafeai Jev, Laya, and System One model news? Our write-up covers what this new class of models do, how the two compare, and how to use them on Runware.

Made laya play doom. #laya #mlx #ai #jev #localai
I trained an audio-native, Jev-like classifier on Laya Gemma 4 audio encoder + a 34M projector, so Laya reads audio like text. No transcription and no generation, just typed answers in one pass. vs Whisper-large-v3 → Laya: • Better on yes/no + noul questions • 2.5–8.6× faster • Same WER on phone calls Built for routing, evals, and sitting next to a live voice model with tools. Write-up: #genai #voiceai #jev #laya #google #gemma #gemma4
I started building an open-source version of this AI <> Microduck use case on August 28, before GPT-6 Astra even came out. quackd is an open-source multi-robot CLI that lets you connect all your robots, command them, and let them work together, each with an LLM for a brain (Claude, OpenAI, Gemini, Grok, or local via Ollama or vLLM) and a decision LLM for multiple choice (Jev, Laya, Kev). Drives Microduck, Open Duck Mini, LeRobot, XLeRobot, AlohaMini, ToddlerBot, or any ROS 2 base from a laptop, offboard.
Project: quackd→Laya 现在通过 Boundless 上线 Vercel AI Gateway:从「生成答案」到「直接做决定」 继 DeepSeek、GLM 之后,Laya 是一个很好的补充 它不负责聊天,而是专门做判断的 open-weight model:分流工单、筛销售线索、排反馈优先级,适合 agent 和各种 workflow 越来越多模型正在通过 Boundless 进入 Vercel 的开发者生态
Introducing LibLayaX. Fast local AI decisions inside your application: a shared library and C API built on laya.cpp that runs the Laya typed-decision model. No server, no Python. Windows, Linux, macOS. x64 and ARM64. CPU or GPU #LocalAI #OpenSource #AI
Project: LibLayaX→Tricking Clef, Jev, Kev and Laya
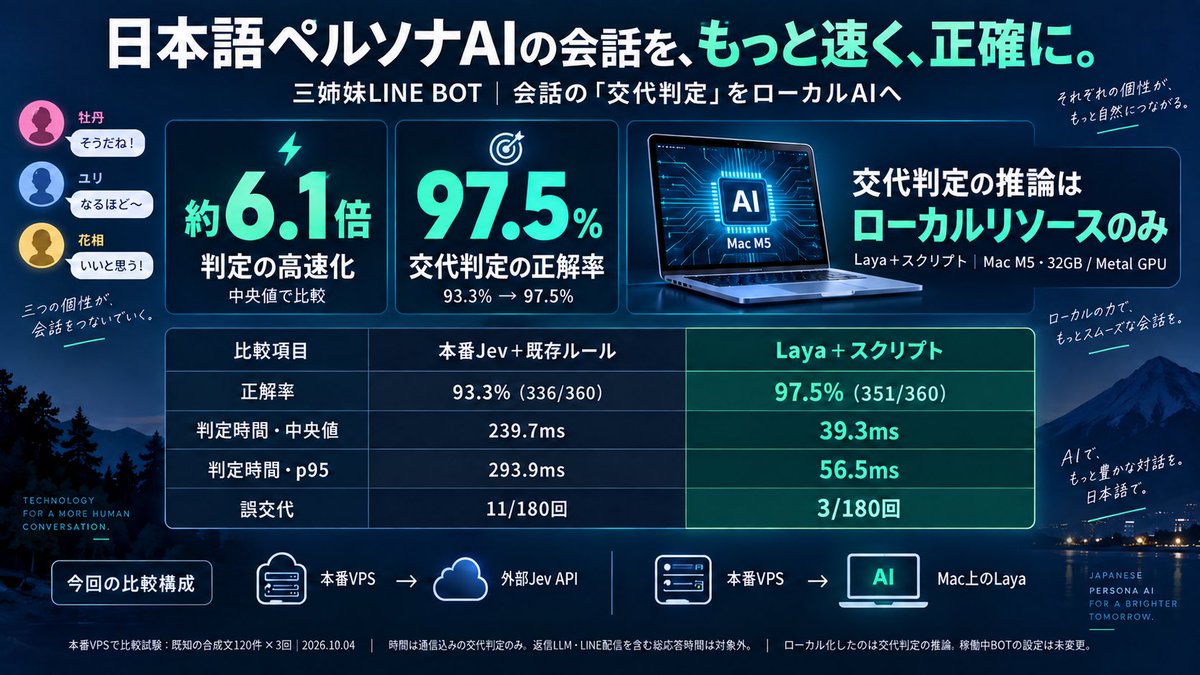
Laya、LLM機のリソース9950X 128GBを活かすために利用してみてみたんだけど、チョイ負けてたからMacBook Proで学習何回もした。見事にJevを置き換えられるレベルになった。
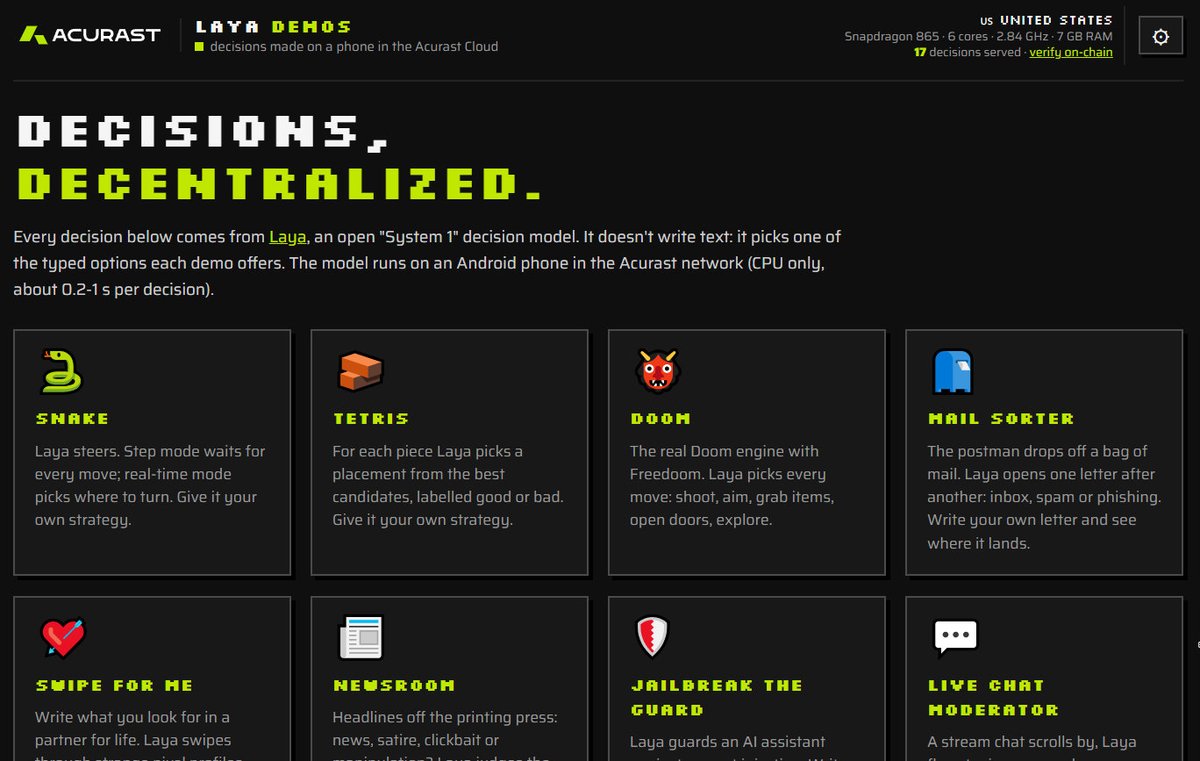
I just tried the Laya Demos by @Acurast, and it's mindblowing to see what would AI and decentralized computing looks like in the real world. 3 mini-sections to explain why this is huge: 1. What's Laya and how does it work? 2. What's $ACU role in all of that? 3. What's the impact on ACU token price? Let's dive in. 1. What's Laya and how does it work? Laya - built by ConvAI Innovations and run by Acurast - is an open-weights decision model, not a chatbot. How things work with Laya: Laya picks one and returns probabilities. No essay, no chat completion. About 0.2-1 second on CPU only. You can see the loop demo live, actually: Snake, Tetris, Doom, mail sort (inbox / spam / phishing), newsroom labels, a prompt-injection guard, chat moderation. No signup required. Every answer comes from a real Android phone on the Acurast network, with country, chip, decisions served, and an on-chain link. A decision service that used to imply a data center, fits on one phone, somewhere in the world. 2. What's ACU role in all of that? Essentially, ACU is how that gets deployed. Scheduling a job pays network fees in ACU. Here's how the economics work with Laya deployments: - Acurast’s very own Cargo: Laya template is under 1 ACU a day for a private instance. - Processors (your smartphones and mine!) earn from inflation (5% a year: 70% staked compute, 10% benchmark rewards) plus a busy bonus when a phone is actually executing. - ACU token holders can delegate stake without hardware. 3. What's the impact on ACU token price? Long term, price only follows if demos become real-life, recurring paid deployments: classifiers, guards, agent backends. - Try it: - Become a compute provider by turning your unused phones into processors and generate ACU in the process:
A 322M parameter model on your CPU can now judge every shell command your coding agent runs, in about 90 ms. I like where this is going. I'm not sold on calling it a security boundary yet. laya-guard sits between the agent and the shell and answers allow, review or block before anything executes. No API call, nothing leaves your machine. It has adapters for Claude Code, Codex CLI, Cursor, Gemini CLI and more. The numbers are decent. Self-reported, it blocked 25 of 27 AgentDojo attacks and kept 92 of 97 benign tasks. At 90 ms you can put it in the hot path without feeling it. Two things keep me cautious. The hook fails open by default, so if the judge breaks, commands just run. A guard that disappears when it crashes is a speed bump. And it judges each command alone. A commenter pointed out that npm test sits on the safe list, but the agent can edit package scripts first and then run it. Write a bad script in step one, run bash in step two, and each step looks harmless. So the check needs repo context, or a human on the risky edge. Cheap local judges are great for catching the obvious stuff. Would you run yours failing open or failing closed?
I started messing with Jev-style classifiers last night. Super easy to get running with llama.cpp! So I put together a simple decider benchmark that checks for toxicity in chat and also looks at a bash command and determines its safety. Laya is ~800Mb on disk and managed about 65% accuracy. Clef is ~15Gb and managed 96%. Still playing around, but I can see lots of applications.
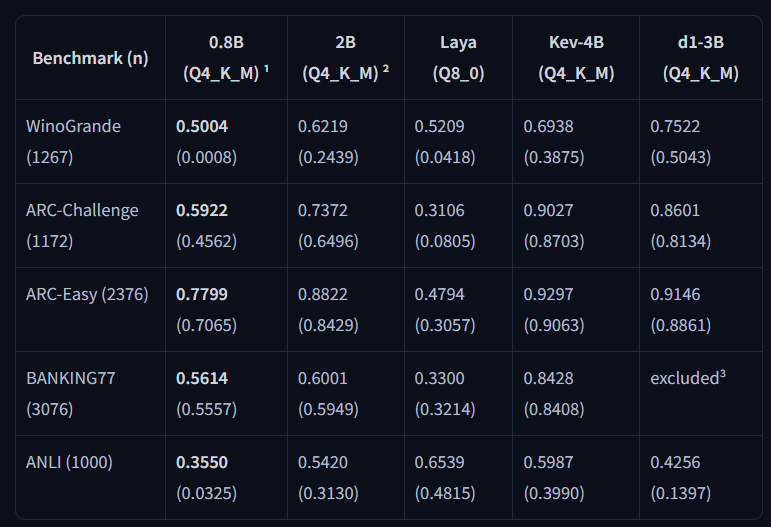
my 0.8B decision model wasn't bad at WinoGrande and ANLI. it was biased. i looked at what it actually answered, not just the accuracy: it picked the second option 2 out of 3 times, and almost never answered "contradiction", even though a third of the answers were. fixed it with 2,400 class balanced rows. Qwen 3.5 0.8B AA Decision: WinoGrande 50.0 -> 55.0 ANLI 35.5 -> 41.2 BANKING77 56.1 -> 54.2 (the cost) vs Laya, Q4_K_M against their Q8_0: ARC-C - 58.7 vs 31.1 ✅ ARC-E - 77.5 vs 47.9 ✅ BANKING77 - 54.2 vs 33.0 ✅ WinoGrande - 55.0 vs 52.1 ✅ ANLI - 41.2 vs 65.4 ❌ 4/5 now. ANLI still loses. updated GGUF, same repo: /v1/systemone, one forward pass, mainline llama.cpp.

LLMs are powerful, but they are also slow and expensive to run. Models like Jev and Laya take a different approach. They are fast, lightweight, and can assign probabilities to predefined outcomes directly from free text. In our study, Laya-Med achieved 85.6% diagnostic accuracy, compared with 83.1% for Google's MedGemma 27B, while running about 64 times faster! And here's the exciting part: inference is so fast that we can build dashboards where the probabilities of different diagnoses change in real time as a physician types clinical notes. Not every medical AI application needs a massive LLM!

everyone was tripping over @typesafeai Jev (amazing tbc).. but in our evals @subquadratic subq-snap-1.1 is winning wrong answers out of 658, sales convos: subq 4 jev 13 gpt-5.6-luna 24 laya 560 (BAD) false alarms: subq 2, jev 12. jev did catch 1 more fault and ran faster
Okay, it's public, and u can try it. Works on JEV (Laya-MLX). Let me know if u like it 😅 ⬇️

update: jevcache isn’t jev only anymore used to need typesafe jev for same intent hits now the judge can be kev, laya, laya-mlx, or any system one - local, no openrouter key for admits oh and we have landing page now:

@avliwii @instantricecook @typesafeai Sorry to hear about your dad. I've built a free, open-source voice browser for Apple-silicon Macs. It can search, click and navigate in Safari/Chrome. Broader Mac control is what I’m working on next. Drop a star if you try it out and like it!
Project: laya-mlx-voice-browser→weekly update: • ~650 downloads in a week • morrowcache started as a jev caching experiment • grew beyond jev → supports laya, laya mlx, kev + local models • shipped the site • need more people to try it + tell me what sucks fully open source, contributions welcome :)

Introducing a version 50 times faster than Jev, running on your device: laya-mlx! Occupies a maximum of 1G memory only on your device Laya is an open-source classification system similar to Jev, based on text output probabilities I ported it to MLX and made some performance optimizations! In the video, this model is playing Snake on my local M3 Max This model can play Snake at a decision speed of 60 times per second!
Project: laya-mlx→1/ Built layax on @Nandakishorm1's Laya, an open typed-decision model. Laya fits every label into one shared token budget, so wide label sets suffer. layax scores each label separately. Banking77: 0.453 → 0.908, same test rows. Code: Weights:
Project: layax→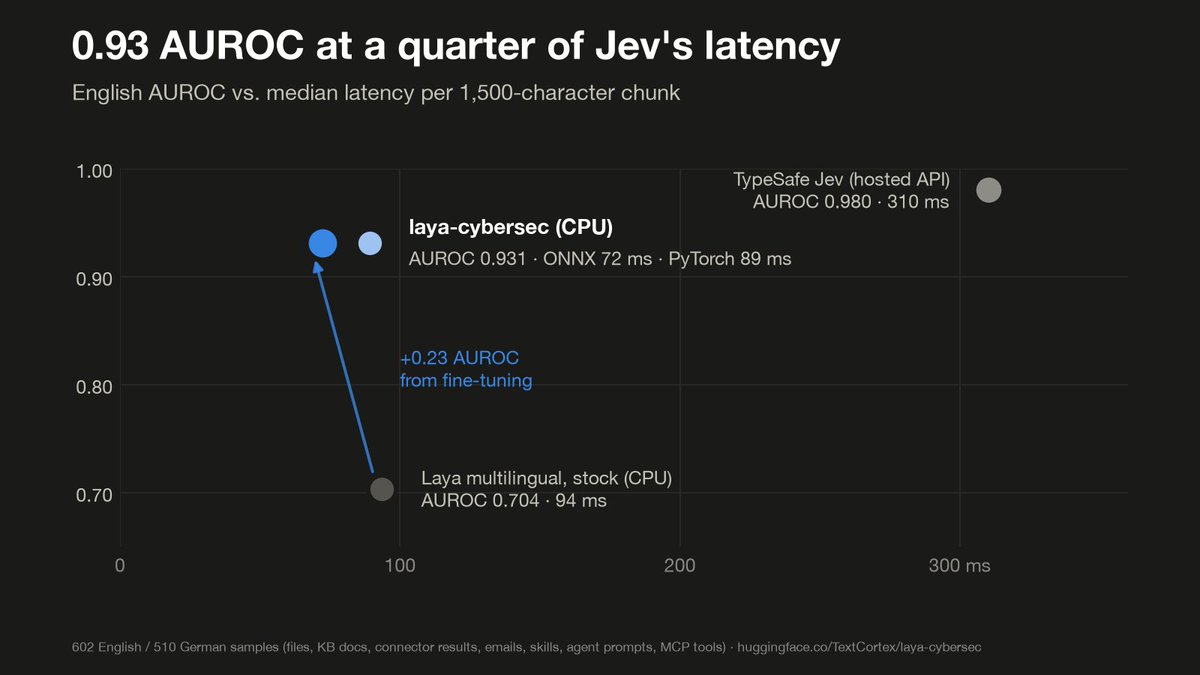
We fine-tuned Laya into laya-cybersec: an open, self-hostable scanner that flags prompt injection and data exfiltration before content reaches your AI agent. Almost same performance as JEV 0.93 AUROC at ~72 ms per chunk on a laptop CPU. 🧵
Run Laya Decision models locally on just 4GB RAM.

Laya is live on Qtum AI Router. Three decision models. You send a ticket, email, or JSON plus typed questions. You get a structured answer, not a paragraph. • laya — English, 512 tokens • laya-multilingual 100+ languages, 1024 tokens • laya-typed-decisions specialist workflows, 1024 tokens 21 credits / 1M input tokens. Output is free. Same key, same balance, hosted on Qtum hardware. Use it for triage, tool routing, urgency scoring, and model-tier gates. Let System 1 decide. Keep the big model for the work that needs it.

I made Laya (Jev-like model) play Breakout, Every paddle move is a live decision from an open 322M System One model (convaiinnovations/laya) running locally on Windows laptop, ~70 decisions/sec on an RTX 5080, zero cloud, $0. Code 👉
Project: laya-breakout→@srhtkrg laya-mlx denedim, openjev denedim localde, apiye bağımlı olmama opsiyonu var aslında biraz

I ran the Laya model on llama.cpp to test the game of Snake, and the results were excellent. The speed was fast, and even on my laptop with an AMD Radeon 780M Graphics, it ran smoothly. Thanks @chenchengpro game code. #Jev #Laya #TypeSafe #llamacpp #LocalLLM
🚀 Day 21/100 of #100DaysOfCode Today’s progress: DSA : > POTD Dev : - Read about tool and tool calling in Langchain. - Read and learned about JEV - implemented Laya-mlx [ open source version of JEV ] I was occupied with college work until this evening. I’ll get back to you tomorrow.
@mugeimunou ローカルjevが動くならcanisterにやらせなくてもいいと思います。 これならmacで動きますよ Layaとopenjev(151M)なら動きました。 openjevの方はqueryでも52token入れれて面白いんですけど性能がw
Project: laya-mlx→Posted a Laya demo on X? Mention “Laya” and it gets picked up automatically, or submit the project.


